 By
Deep search now finds the answer to 96.5% of SimpleQA questions, and it costs 2 credits a call instead of 5. On the Startup plan that's $1.78 per 1,000 requests. On Essential it's $5.33.
browserfoundry is built by Keirolabs, and this is the same /deep endpoint on the same key. The full release is also on keirolabs.cloud.
What changed in deep search
POST /api/v2/deep does the reading your agent used to do. It searches several engines, opens the top pages, scores every passage for how likely it is to hold the answer, and returns the best ones packed into a token budget (1,000 by default).
Three things are new:
- Smaller evidence. The evidence block averages 896 tokens. Your model reads a few hundred tokens instead of whole pages.
answer_statuson every response:found,weakornot_found. When deep saysfound, the answer is in the evidence 97.3% of the time (183 of 188), so your agent can trust it and spend its effort on the rest.- Early stopping. When two independent sites agree on the answer, deep stops reading. That happened on 143 of 200 calls, at a median of 6.3 s. Overall median latency is 7.5 s, and the 90th percentile is 18.1 s.
The price drops from 5 credits to 2 on every plan.
The results: 96.5% on SimpleQA
We ran 200 questions from OpenAI's SimpleQA test set, none of which were used while building or tuning deep.
| Answer found | Exact match | |
|---|---|---|
| Evidence only (~900 tokens, what an agent reads) | 94.0% (188/200) | 82.5% (165/200) |
| Whole response (evidence + page text) | 96.5% (193/200) | 90.0% (180/200) |
Exact match means the gold answer appears verbatim. Answer found also counts variant forms, such as date order, abbreviations and numerals versus words, as accepted by an LLM judge. It doesn't count answers you'd have to compute, or partial answers. This measures whether the answer is present in what comes back, not whether a model reading it would answer correctly.
The runner, the judge prompt and every question's result are open: github.com/Keirolabs-API/deep-search-benchmark.
How deep compares on price and accuracy
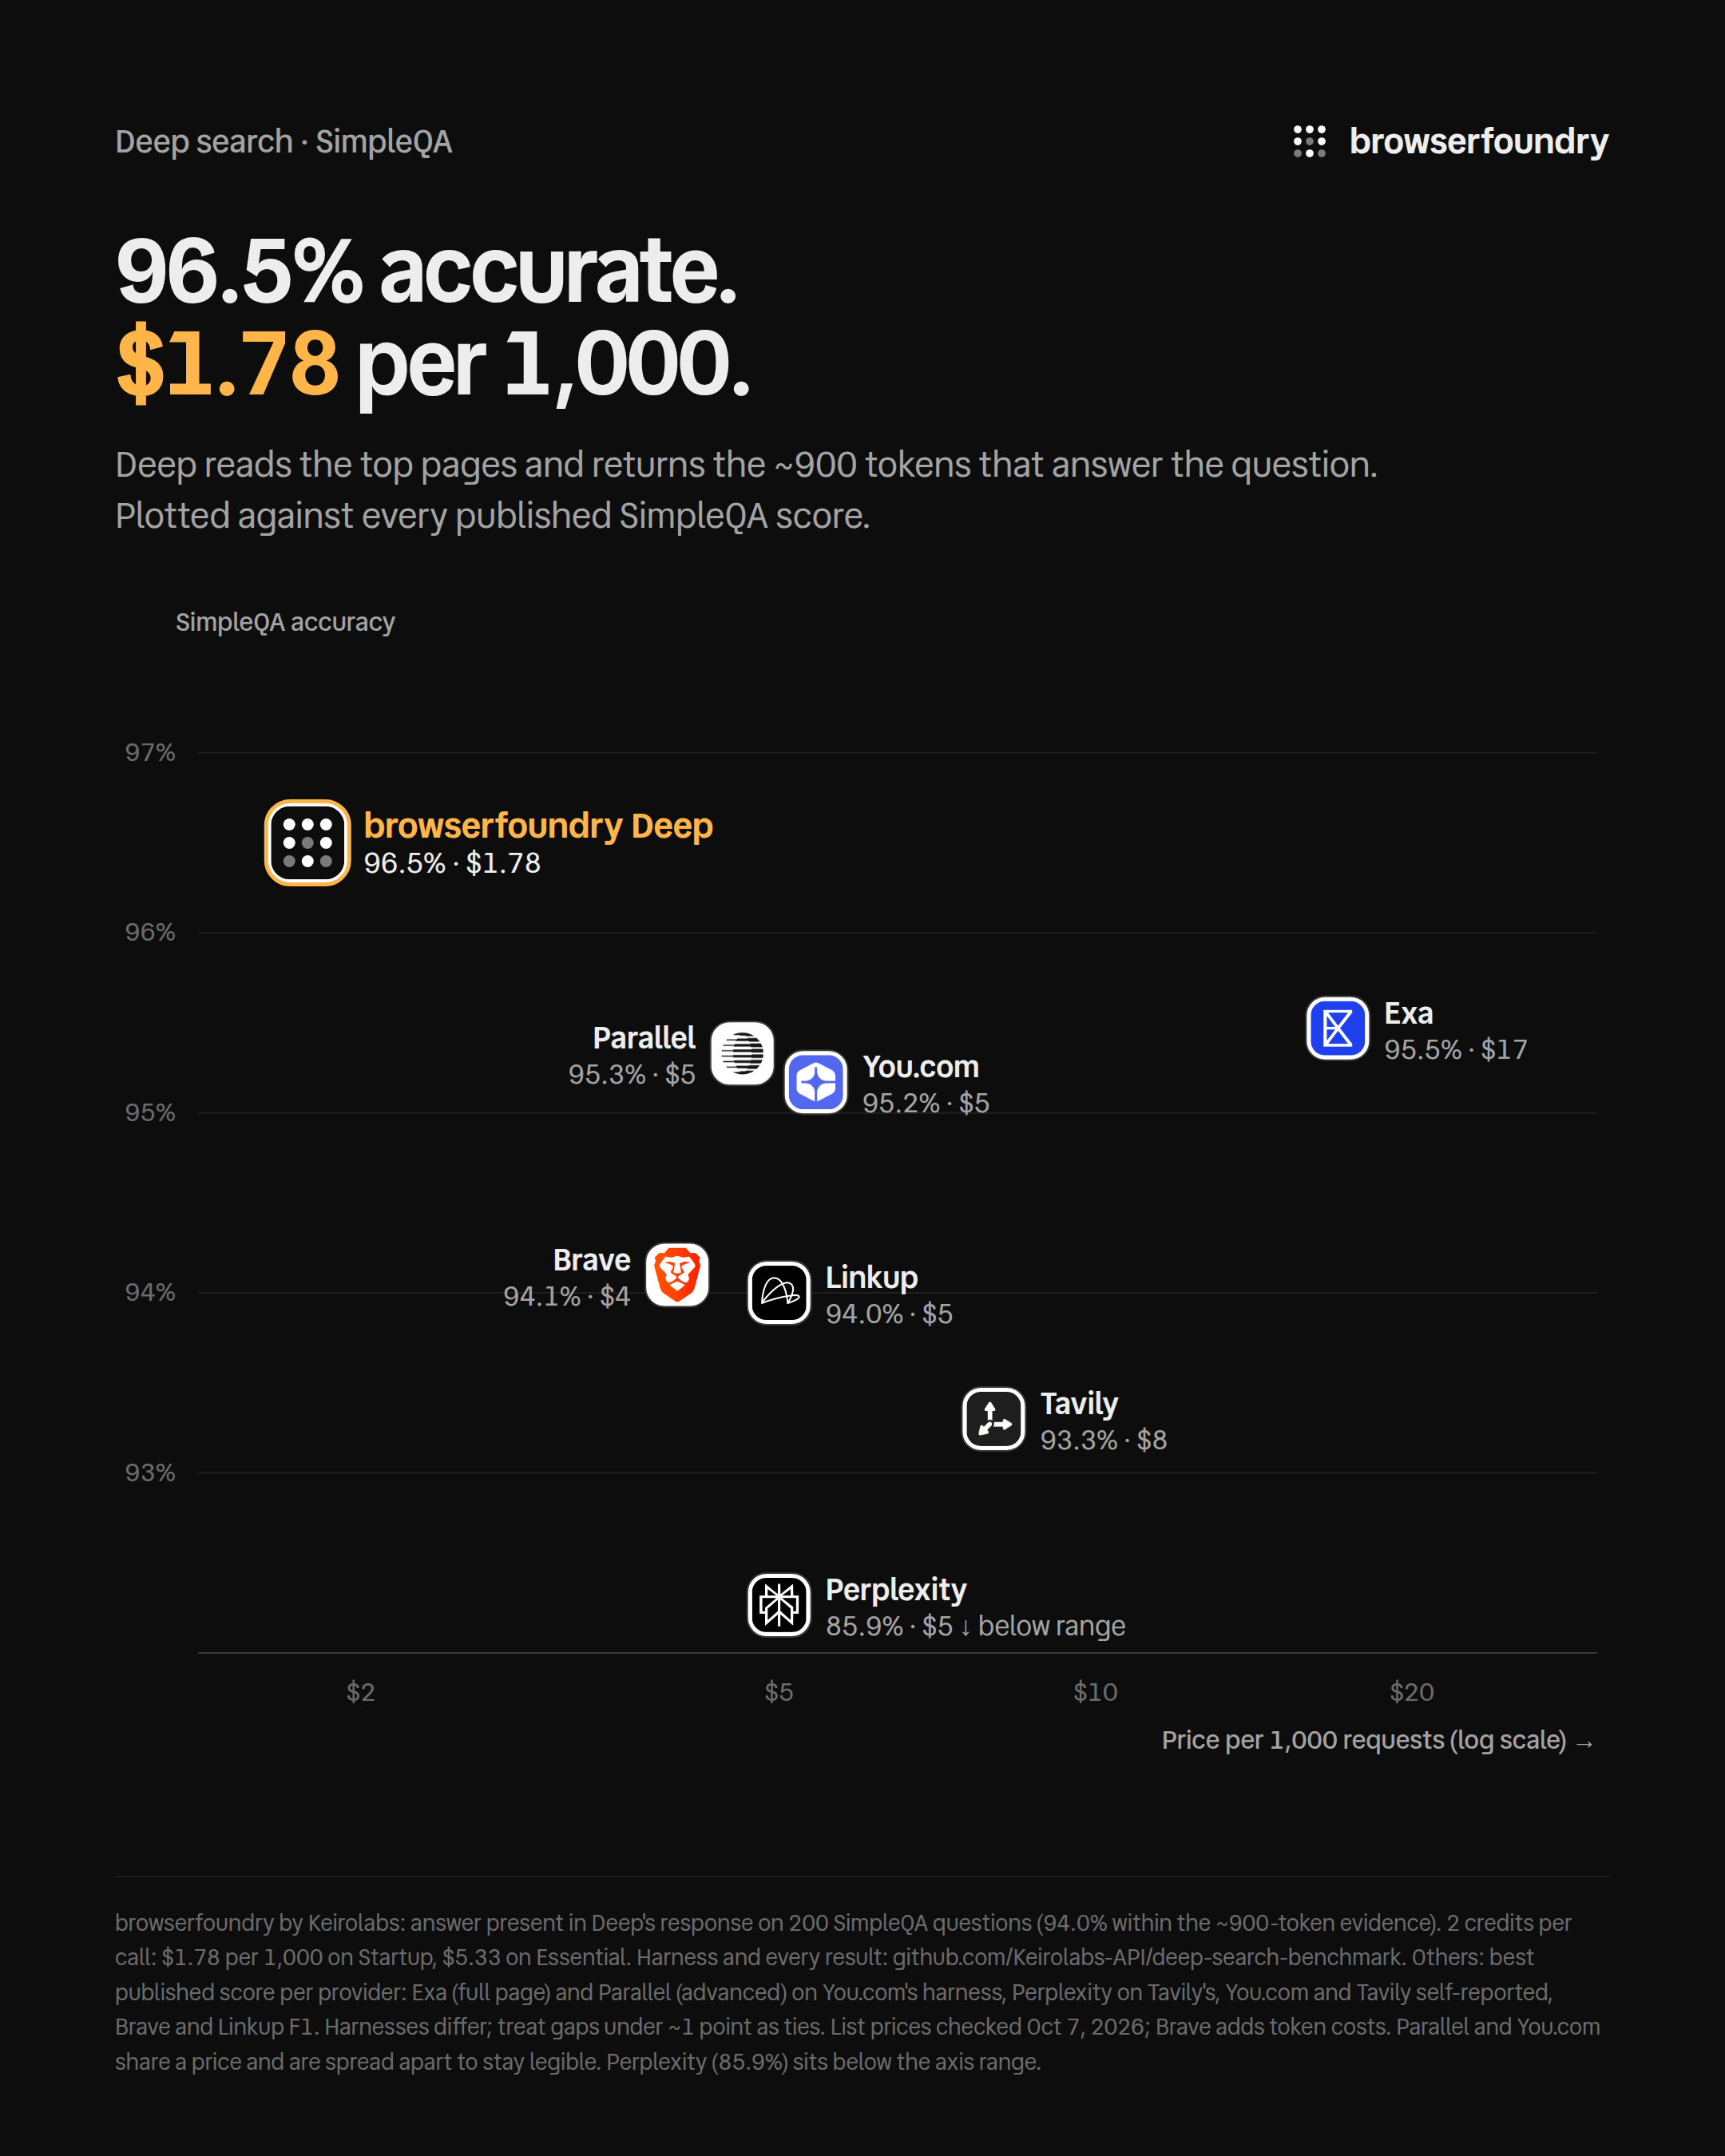
| Provider | SimpleQA | Price per 1,000 | Source |
|---|---|---|---|
| browserfoundry deep | 96.5% | $1.78 (Startup) / $5.33 (Essential) | own harness, answer present |
| Exa (full page) | 95.47% | ~$17 | You.com's harness |
| Parallel (advanced) | 95.33% | $5 | You.com's harness |
| You.com (Highlights) | 95.17% | $5 | self-reported |
| Brave AI Grounding | 94.1% (F1) | $4 + tokens | self-reported |
| Linkup (fast) | 94% (F1) | $5 | self-reported |
| Tavily | 93.3% | $8 | self-reported |
| Perplexity Search | 85.92% | $5 | Tavily's harness |
Read the top of this table as a tie: every vendor runs SimpleQA a little differently, and gaps under about a point are inside run-to-run noise. What isn't noise is the price. At this accuracy, deep is the only option under $5 per 1,000. Competitor prices are list pay-as-you-go rates checked on October 7, 2026.
Lite: $0.10 per 1,000
Lite is the other end of the scale. It returns 10 results for $0.10 per 1,000 on Essential, and less on bigger plans.
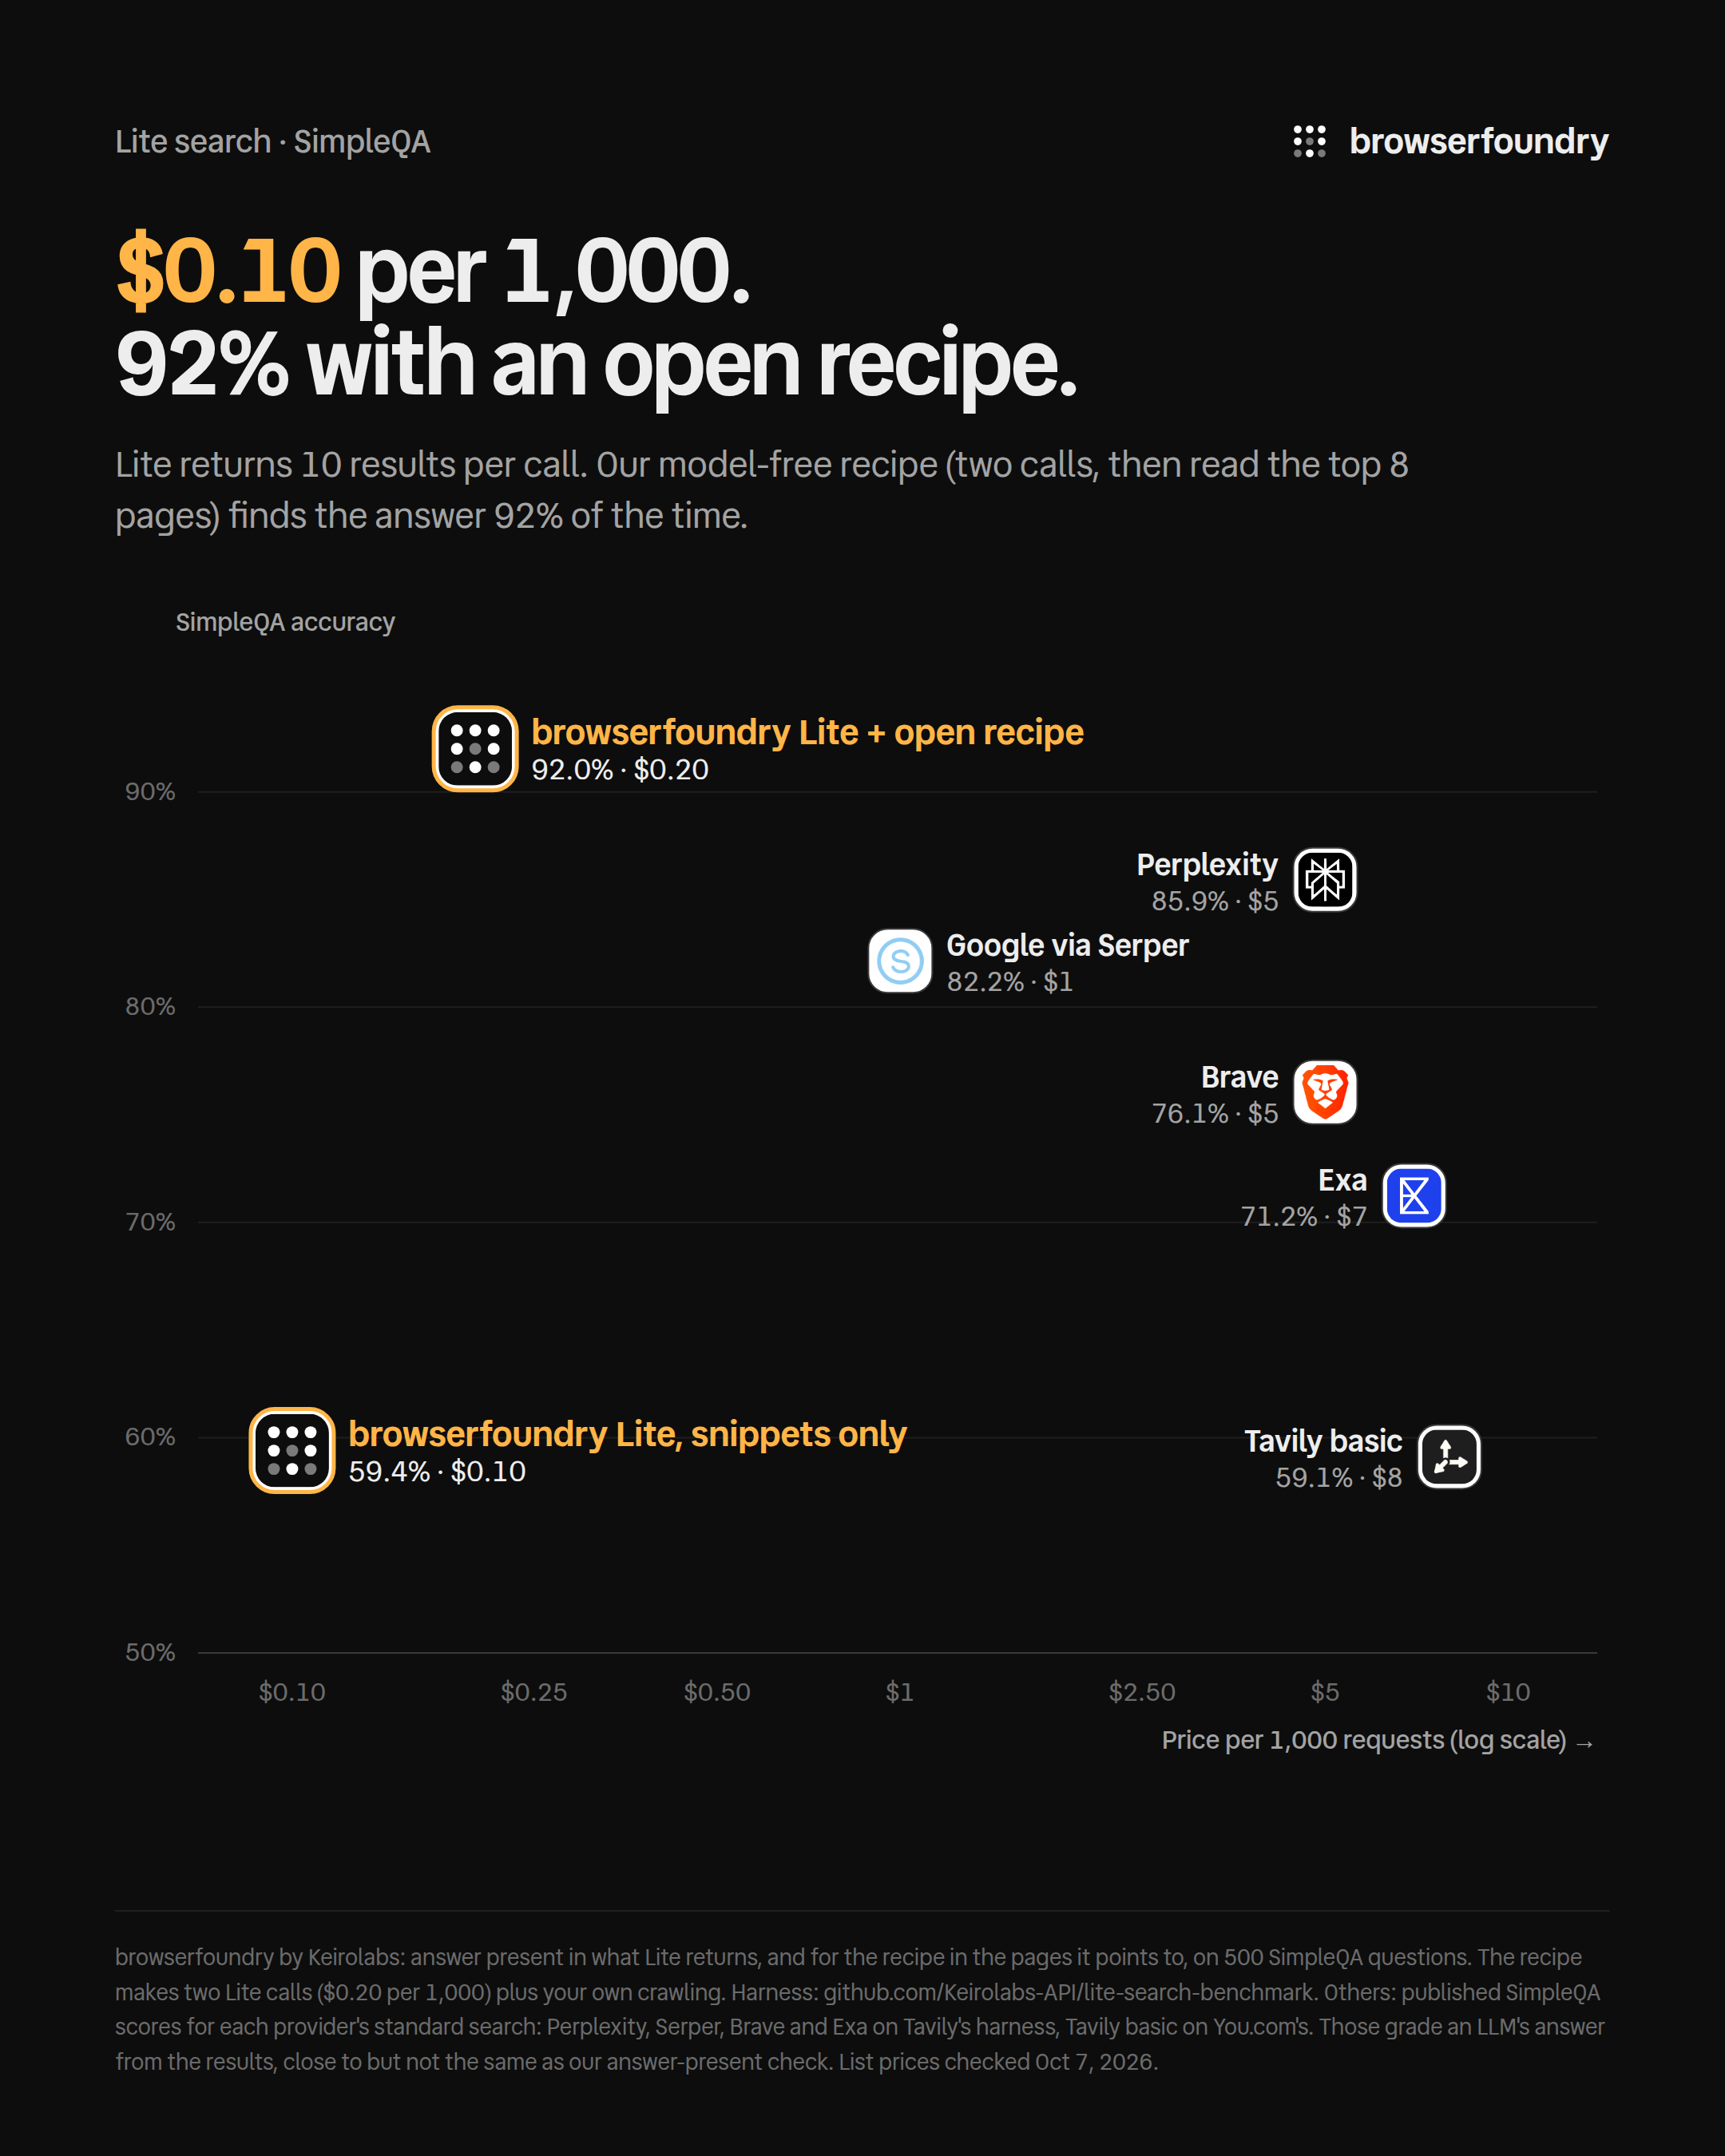
On 500 SimpleQA questions, the answer is in Lite's snippets 59.4% of the time. We published a model-free recipe on top of it: two Lite calls, Wikipedia's search, then read the top 8 pages. That reaches 92.0% at $0.20 per 1,000 plus your own crawling. Open harness: github.com/Keirolabs-API/lite-search-benchmark.
| Answer found | Tokens to read | |
|---|---|---|
| Lite results only | 59.4% | ~550 |
| Lite + top 5 pages crawled | 84.6% | ~13,800 |
| Lite + open recipe, top 8 pages crawled | 92.0% | ~37,000 |
| Lite + recipe, then BM25 picks ~900 tokens | 75.6% | ~900 |
| Deep, evidence only | 94.0% | ~900 |
The last two rows give the same ~900-token budget. Keyword picking keeps the answer 75.6% of the time; deep's passage scoring keeps it 94.0%. Lite is the right call when you have a crawler and want the cheapest results. Deep is the right call when your agent should read a short block and move on.
Try it
curl -X POST https://api.keirolabs.cloud/api/v2/deep \
  -H "Authorization: Bearer keiro_YOUR_KEY" \
  -H "Content-Type: application/json" \
  -d '{"query": "Who cheated in the 1993 Comrades Marathon?", "budget": 1000}'
Free accounts get 750 credits every month with no card, which is enough for 375 deep calls. Get a key at platform.keirolabs.cloud, or see pricing.
FAQ
How accurate is browserfoundry deep search on SimpleQA?
The answer is in deep's response for 193 of 200 SimpleQA questions (96.5%), and in the ~900-token evidence block alone for 188 (94.0%). The runner and every result are open at github.com/Keirolabs-API/deep-search-benchmark.
How much does deep search cost?
2 credits per call on every plan: $1.78 per 1,000 requests on Startup and $5.33 per 1,000 on Essential. 750 free credits cover 375 deep calls.
What does answer_status mean?
Every deep response is marked found, weak or not_found. On the benchmark, found was right 97.3% of the time (183 of 188), so an agent can accept found answers and spend its retries on the rest.
Is 96.5% better than Exa, Parallel or You.com?
Treat the top as a tie: Exa (95.47%), Parallel (95.33%) and You.com (95.17%) published on different harnesses, and gaps under about a point are noise. The difference is price: $5 to $17 per 1,000 for them, $1.78 for deep on Startup.
Is this the same as Keirolabs deep search?
Yes. browserfoundry is built by Keirolabs and runs on the same API, so the /deep endpoint, results and prices are identical.